OCR Benchmark
Gemini 4 Neon leads Roboflow's Vision Evals OCR benchmark at 88.1% (low effort, preliminary single run), with GPT-6.2 Sol at 87.5% and GPT-6.2 Astra at 87.4%. At high reasoning effort, Gemini 4 Carbon reaches 89.7%.
Evals updated November 19, 2026Pricing updated November 22, 2026
| 1 | high | 89.7% | 85.2% | 99.1% | 93.9% | 85.2% | 11.3K | $0.102 | 91.40s | ||
| 2 | high | 89.2% | 83.5% | 98.8% | 93.9% | 86.0% | 6.5K | $0.082 | 49.87s | ||
| 3 | GPT-6.2 SolNEW | high | 89.0% | 83.5% | 98.5% | 94.5% | 83.4% | 2.6K | $0.010 | 12.73s | |
| 4 | high | 88.3% | 80.9% | 98.6% | 94.9% | 85.0% | 2.8K | $0.049 | 19.71s | ||
| 5 | low | 88.1% | 80.9% | 98.5% | 93.8% | 86.3% | 2.4K | $0.021 | 20.95s | ||
| 6 | high | 88.0% | 80.0% | 98.8% | 94.8% | 84.7% | 3.2K | $0.022 | 21.29s | ||
| 7 | GPT-6.2 SolNEW | low | 87.5% | 80.0% | 98.1% | 94.2% | 83.6% | 2.2K | $0.0059 | 8.15s | |
| 8 | low | 87.4% | 80.4% | 98.8% | 93.7% | 82.7% | 2.2K | $0.024 | 8.73s | ||
| 9 | high | 87.2% | 80.9% | 95.3% | 93.1% | 83.7% | 4.6K | $0.026 | 17.18s | ||
| 10 | low | 87.2% | 80.4% | 96.6% | 93.0% | 84.2% | 1.5K | $0.0053 | 7.54s | ||
| 11 | low | 86.7% | 78.7% | 96.1% | 93.6% | 83.9% | 2.2K | $0.0089 | 12.82s | ||
| 12 | low | 85.7% | 78.3% | 95.5% | 92.6% | 81.5% | 1.5K | $0.0051 | 7.70s | ||
| 13 | high | 84.8% | 77.4% | 97.9% | 94.1% | 72.9% | 3.0K | $0.043 | 12.14s | ||
| 14 | high | 84.4% | 74.8% | 97.0% | 93.4% | 79.2% | 2.9K | $0.0066 | 18.75s | ||
| 15 | low | 81.9% | 70.9% | 96.7% | 91.5% | 77.6% | 2.2K | $0.0033 | 11.45s | ||
| 16 | high | 79.9% | 69.6% | 96.1% | 94.1% | 61.1% | 3.1K | $0.023 | 8.96s | ||
| 17 | low | 79.7% | 70.9% | 95.4% | 88.0% | 72.5% | 4.0K | $0.0079 | 15.98s | ||
| 18 | low | 79.5% | 64.8% | 94.7% | 92.8% | 74.5% | 2.7K | $0.030 | 9.03s | ||
| 19 | high | 78.8% | 71.7% | 91.9% | 90.6% | 59.2% | 3.7K | $0.010 | 10.18s | ||
| 20 | high | 78.7% | 70.9% | 94.1% | 90.9% | 58.6% | 10.5K | $0.039 | 79.76s | ||
| 21 | low | 78.3% | 67.8% | 96.7% | 91.5% | 61.0% | 2.7K | $0.016 | 5.94s | ||
| 22 | high | 78.2% | 66.5% | 94.2% | 89.2% | 71.3% | 4.1K | $0.0084 | 17.40s | ||
| 23 | low | 77.8% | 60.9% | 95.9% | 91.8% | 75.5% | 2.3K | $0.034 | 12.11s | ||
| 24 | high | 77.6% | 59.6% | 97.5% | 91.7% | 76.8% | 3.3K | $0.084 | 39.33s | ||
| 25 | high | 77.4% | 68.7% | 90.3% | 89.3% | 62.1% | 4.8K | $0.014 | 19.94s | ||
| 26 | low | 76.7% | 71.7% | 90.0% | 86.8% | 56.2% | 2.5K | $0.013 | 7.39s | ||
| 27 | high | 76.0% | 70.9% | 88.3% | 90.3% | 45.9% | 4.7K | $0.059 | 23.46s | ||
| 28 | high | 75.8% | 56.5% | 96.0% | 90.4% | 76.7% | 3.1K | $0.016 | 29.89s | ||
| 29 | low | 75.8% | 58.3% | 95.7% | 89.5% | 74.4% | 2.3K | $0.0069 | 10.55s | ||
| 30 | high | 75.5% | 69.6% | 85.4% | 88.1% | 53.3% | 4.5K | $0.031 | 14.36s | ||
| 31 | high | 75.3% | 69.1% | 95.2% | 89.5% | 43.4% | 3.0K | $0.051 | 10.22s | ||
| 32 | low | 74.3% | 67.4% | 93.2% | 90.5% | 40.1% | 3.4K | $0.034 | 12.30s | ||
| 33 | high | 74.2% | 72.2% | 87.7% | 89.2% | 33.3% | 3.4K | $0.075 | 18.57s | ||
| 34 | low | 74.0% | 63.9% | 95.2% | 85.4% | 59.0% | 2.3K | $0.0077 | 18.12s | ||
| 35 | low | 73.9% | 74.8% | 91.1% | 86.7% | 29.4% | 1.8K | $0.0032 | 5.58s | ||
| 36 | high | 73.1% | 68.7% | 90.8% | 83.9% | 47.1% | 3.2K | $0.026 | 18.64s | ||
| 37 | high | 73.1% | 69.1% | 90.0% | 87.5% | 36.9% | 5.3K | $0.013 | 21.69s | ||
| 38 | low | 72.9% | 64.3% | 84.7% | 89.2% | 46.5% | 2.7K | $0.039 | 7.94s | ||
| 39 | low | 72.8% | 73.5% | 91.3% | 86.1% | 26.4% | 2.2K | $0.0049 | 12.60s | ||
| 40 | low | 72.6% | 67.8% | 88.5% | 82.0% | 52.0% | 1.9K | $0.010 | 8.51s | ||
| 41 | low | 72.3% | 70.9% | 90.2% | 85.7% | 31.6% | 2.8K | $0.041 | 9.77s | ||
| 42 | high | 71.8% | 61.7% | 94.8% | 81.6% | 59.6% | 5.7K | $0.028 | 78.42s | ||
| 43 | low | 71.8% | 68.3% | 89.4% | 82.9% | 42.5% | 1.8K | $0.0030 | 5.58s | ||
| 44 | high | 71.2% | 66.1% | 88.6% | 82.1% | 46.4% | 3.6K | $0.0063 | 9.60s | ||
| 45 | Muse EmberNEW | high | 70.5% | 63.0% | 90.2% | 87.2% | 35.9% | 5.2K | $0.0017 | 9.69s | |
| 46 | low | 70.4% | 62.6% | 91.8% | 88.0% | 33.3% | 3.6K | $0.0086 | 26.68s | ||
| 47 | high | 69.8% | 62.2% | 86.8% | 87.2% | 35.2% | 5.1K | $0.015 | 50.96s | ||
| 48 | Muse EmberNEW | low | 69.5% | 61.7% | 95.5% | 85.1% | 35.3% | 3.7K | $0.0010 | 6.66s | |
| 49 | low | 68.8% | 60.4% | 90.1% | 86.1% | 33.9% | 3.3K | $0.0076 | 6.53s | ||
| 50 | high | 68.8% | 47.4% | 91.0% | 85.3% | 68.7% | 3.4K | $0.018 | 26.43s | ||
| 51 | low | 68.7% | 60.4% | 89.3% | 87.0% | 31.5% | 3.6K | $0.0086 | 13.97s | ||
| 52 | high | 68.6% | 61.7% | 85.1% | 86.7% | 30.7% | 4.9K | $0.014 | 26.58s | ||
| 53 | high | 68.6% | 58.3% | 91.4% | 88.2% | 32.2% | 4.9K | $0.014 | 16.62s | ||
| 54 | low | 68.0% | 56.1% | 92.7% | 85.2% | 40.5% | 2.8K | $0.022 | 8.49s | ||
| 55 | low | 67.6% | 60.0% | 89.0% | 85.5% | 29.5% | 3.1K | $0.0061 | 5.83s | ||
| 56 | high | 67.5% | 60.4% | 81.6% | 85.7% | 31.4% | 5.2K | $0.015 | 13.76s | ||
| 57 | low | 66.7% | 45.6% | 88.3% | 83.4% | 65.7% | 2.4K | $0.0077 | 9.27s | ||
| 58 | low | 66.3% | 48.7% | 76.3% | 83.8% | 60.6% | 2.7K | $0.0075 | 5.47s | ||
| 59 | high | 65.8% | 47.8% | 85.2% | 88.7% | 42.6% | 3.6K | $0.043 | 18.60s | ||
| 60 | low | 65.8% | 64.3% | 87.5% | 75.8% | 31.9% | 1.6K | $0.0012 | 4.65s | ||
| 61 | high | 65.5% | 58.3% | 89.7% | 81.3% | 30.4% | 4.4K | $0.0042 | 51.00s | ||
| 62 | high | 65.3% | 46.5% | 94.7% | 85.3% | 45.8% | 4.0K | $0.0010 | 12.27s | ||
| 62 | high | 65.3% | 46.1% | 92.3% | 83.9% | 51.6% | 4.0K | $0.048 | 29.09s | ||
| 64 | low | 65.2% | 60.9% | 86.8% | 76.3% | 35.9% | 825 | $0.0046 | 6.88s | ||
| 65 | high | 64.6% | 63.0% | 87.3% | 78.3% | 20.6% | 2.8K | $0.025 | 21.02s | ||
| 66 | low | 63.9% | 63.9% | 90.5% | 80.2% | 7.6% | 1.8K | $0.0024 | 6.96s | ||
| 67 | low | 63.6% | 54.4% | 89.5% | 86.4% | 14.8% | 5.7K | $0.023 | 38.94s | ||
| 68 | low | 63.6% | 43.5% | 91.7% | 82.0% | 52.2% | 2.5K | $0.019 | 12.68s | ||
| 69 | high | 62.9% | 51.3% | 87.3% | 79.3% | 37.4% | 2.7K | $0.0008 | 15.40s | ||
| 70 | high | 62.5% | 44.4% | 84.0% | 81.0% | 50.0% | 4.1K | $0.0013 | 26.32s | ||
| 71 | high | 62.3% | 56.1% | 83.8% | 75.7% | 31.7% | 4.5K | $0.0004 | 45.77s | ||
| 72 | high | 62.1% | 54.8% | 67.0% | 83.5% | 23.6% | 3.5K | $0.038 | 16.14s | ||
| 73 | high | 61.8% | 43.9% | 80.4% | 82.9% | 43.4% | 6.2K | $0.033 | 36.90s | ||
| 74 | high | 61.7% | 50.4% | 86.1% | 76.0% | 40.3% | 5.6K | $0.011 | 48.85s | ||
| 75 | low | 61.5% | 53.0% | 70.8% | 82.4% | 24.2% | 3.0K | $0.025 | 9.48s | ||
| 76 | low | 61.2% | 44.8% | 93.0% | 82.2% | 32.0% | 3.1K | $0.0006 | 9.16s | ||
| 77 | high | 61.2% | 50.9% | 88.7% | 85.7% | 9.4% | 6.5K | $0.030 | 70.49s | ||
| 78 | low | 60.7% | 54.4% | 82.9% | 80.2% | 14.8% | 2.8K | $0.0016 | 11.10s | ||
| 79 | low | 60.6% | 50.0% | 89.0% | 84.4% | 11.0% | 3.2K | $0.011 | 18.68s | ||
| 80 | high | 60.6% | 43.9% | 89.9% | 82.6% | 30.5% | 5.1K | $0.105 | 38.49s | ||
| 81 | low | 60.3% | 53.5% | 86.7% | 75.8% | 23.1% | 1.8K | $0.0009 | 7.87s | ||
| 82 | high | 60.1% | 54.4% | 78.4% | 80.0% | 13.7% | 4.4K | $0.0041 | 36.70s | ||
| 83 | high | 59.8% | 49.1% | 80.9% | 74.9% | 36.8% | 4.4K | $0.0097 | 102.63s | ||
| 84 | low | 59.8% | 41.7% | 80.0% | 78.2% | 47.4% | 2.5K | $0.0004 | 9.31s | ||
| 85 | high | 59.5% | 54.8% | 88.3% | 76.6% | 11.6% | 3.4K | $0.015 | 13.98s | ||
| 86 | low | 59.4% | 52.2% | 88.6% | 78.3% | 13.1% | 2.7K | $0.0078 | 6.54s | ||
| 87 | low | 58.9% | 50.9% | 83.0% | 73.2% | 29.4% | 1.9K | $0.0004 | 7.55s | ||
| 88 | low | 58.6% | 43.0% | 75.1% | 78.1% | 39.3% | 4.5K | $0.0053 | 6.35s | ||
| 89 | low | 58.4% | 42.2% | 88.0% | 80.7% | 26.6% | 2.5K | $0.025 | 10.28s | ||
| 90 | high | 57.5% | 47.8% | 86.1% | 80.9% | 7.0% | 3.4K | $0.013 | 22.48s | ||
| 91 | low | 57.1% | 47.8% | 85.4% | 80.3% | 6.1% | 2.3K | $0.0065 | 10.50s | ||
| 92 | high | 56.9% | 37.4% | 80.2% | 77.3% | 41.9% | 3.4K | $0.021 | 21.67s | ||
| 93 | low | 56.4% | 48.3% | 84.3% | 71.0% | 24.0% | 2.8K | $0.0013 | 20.59s | ||
| 94 | low | 56.3% | 36.1% | 79.9% | 76.8% | 42.3% | 2.6K | $0.011 | 10.54s | ||
| 95 | high | 56.0% | 44.4% | 77.8% | 69.6% | 38.7% | 3.8K | $0.0080 | 18.90s | ||
| 96 | high | 55.8% | 47.0% | 78.5% | 79.0% | 6.1% | 7.4K | $0.027 | 33.34s | ||
| 97 | high | 55.7% | 33.0% | 83.5% | 77.0% | 43.8% | 5.1K | $0.0041 | 34.65s | ||
| 98 | high | 55.5% | 46.5% | 84.1% | 71.4% | 21.6% | 2.8K | $0.0013 | 21.86s | ||
| 99 | low | 55.4% | 47.4% | 81.5% | 72.0% | 18.6% | 3.4K | $0.0002 | 11.12s | ||
| 100 | high | 55.3% | 50.9% | 72.2% | 72.0% | 14.5% | 4.2K | $0.0002 | 24.14s | ||
| 101 | high | 54.5% | 38.3% | 75.3% | 76.4% | 28.8% | 11.1K | $0.021 | 187.98s | ||
| 102 | Kimi K2.6 | low | 54.4% | 34.8% | 77.9% | 78.5% | 29.8% | 2.5K | $0.0026 | 10.55s | |
| 103 | low | 54.3% | 52.2% | 84.4% | 67.3% | 9.9% | 1.8K | $0.0001 | 5.20s | ||
| 104 | Kimi K2.6 | high | 52.5% | 38.7% | 54.2% | 75.8% | 26.9% | 8.1K | $0.022 | 107.65s | |
| 105 | low | 51.8% | 29.6% | 75.5% | 73.6% | 39.7% | 2.5K | $0.0011 | 8.97s | ||
| 106 | low | 51.5% | 43.0% | 78.0% | 67.5% | 17.7% | 2.7K | $0.0039 | 5.55s | ||
| 107 | low | 51.1% | 41.3% | 77.3% | 73.6% | 4.1% | 2.3K | $0.0035 | 5.44s | ||
| 108 | high | 50.4% | 42.2% | 68.9% | 69.2% | 13.2% | 5.5K | $0.0012 | 59.84s | ||
| 109 | high | 49.9% | 40.4% | 59.9% | 70.2% | 16.8% | 4.9K | $0.0034 | 58.34s | ||
| 110 | low | 49.7% | 41.7% | 72.5% | 68.6% | 9.2% | 2.4K | $0.0004 | 22.21s | ||
| 111 | low | 48.6% | 37.0% | 68.2% | 67.7% | 18.7% | 2.4K | $0.0012 | 9.41s | ||
| 112 | low | 46.1% | 33.5% | 68.9% | 71.7% | 0.0% | 3.2K | $0.0044 | 48.82s | ||
| 113 | DeepSeek V4 Flash Vision Exp | high | 44.7% | 34.8% | 69.3% | 64.3% | 6.1% | 4.9K | $0.0060 | 27.71s | |
| 114 | DeepSeek V4 Flash Vision Exp | low | 44.0% | 34.4% | 65.2% | 64.9% | 3.4% | 5.1K | $0.0062 | 30.11s |
Score vs. cost
OCR score (Overall) against estimated cost per sample, on a log scale. Upper-left is the sweet spot: high quality at low cost.
57 models on the current benchmark · OCR task only, low effort
Example OCR benchmark tasks
Real samples from the benchmark: the image each model sees, the question it is asked, and the ground-truth answer it is scored against.
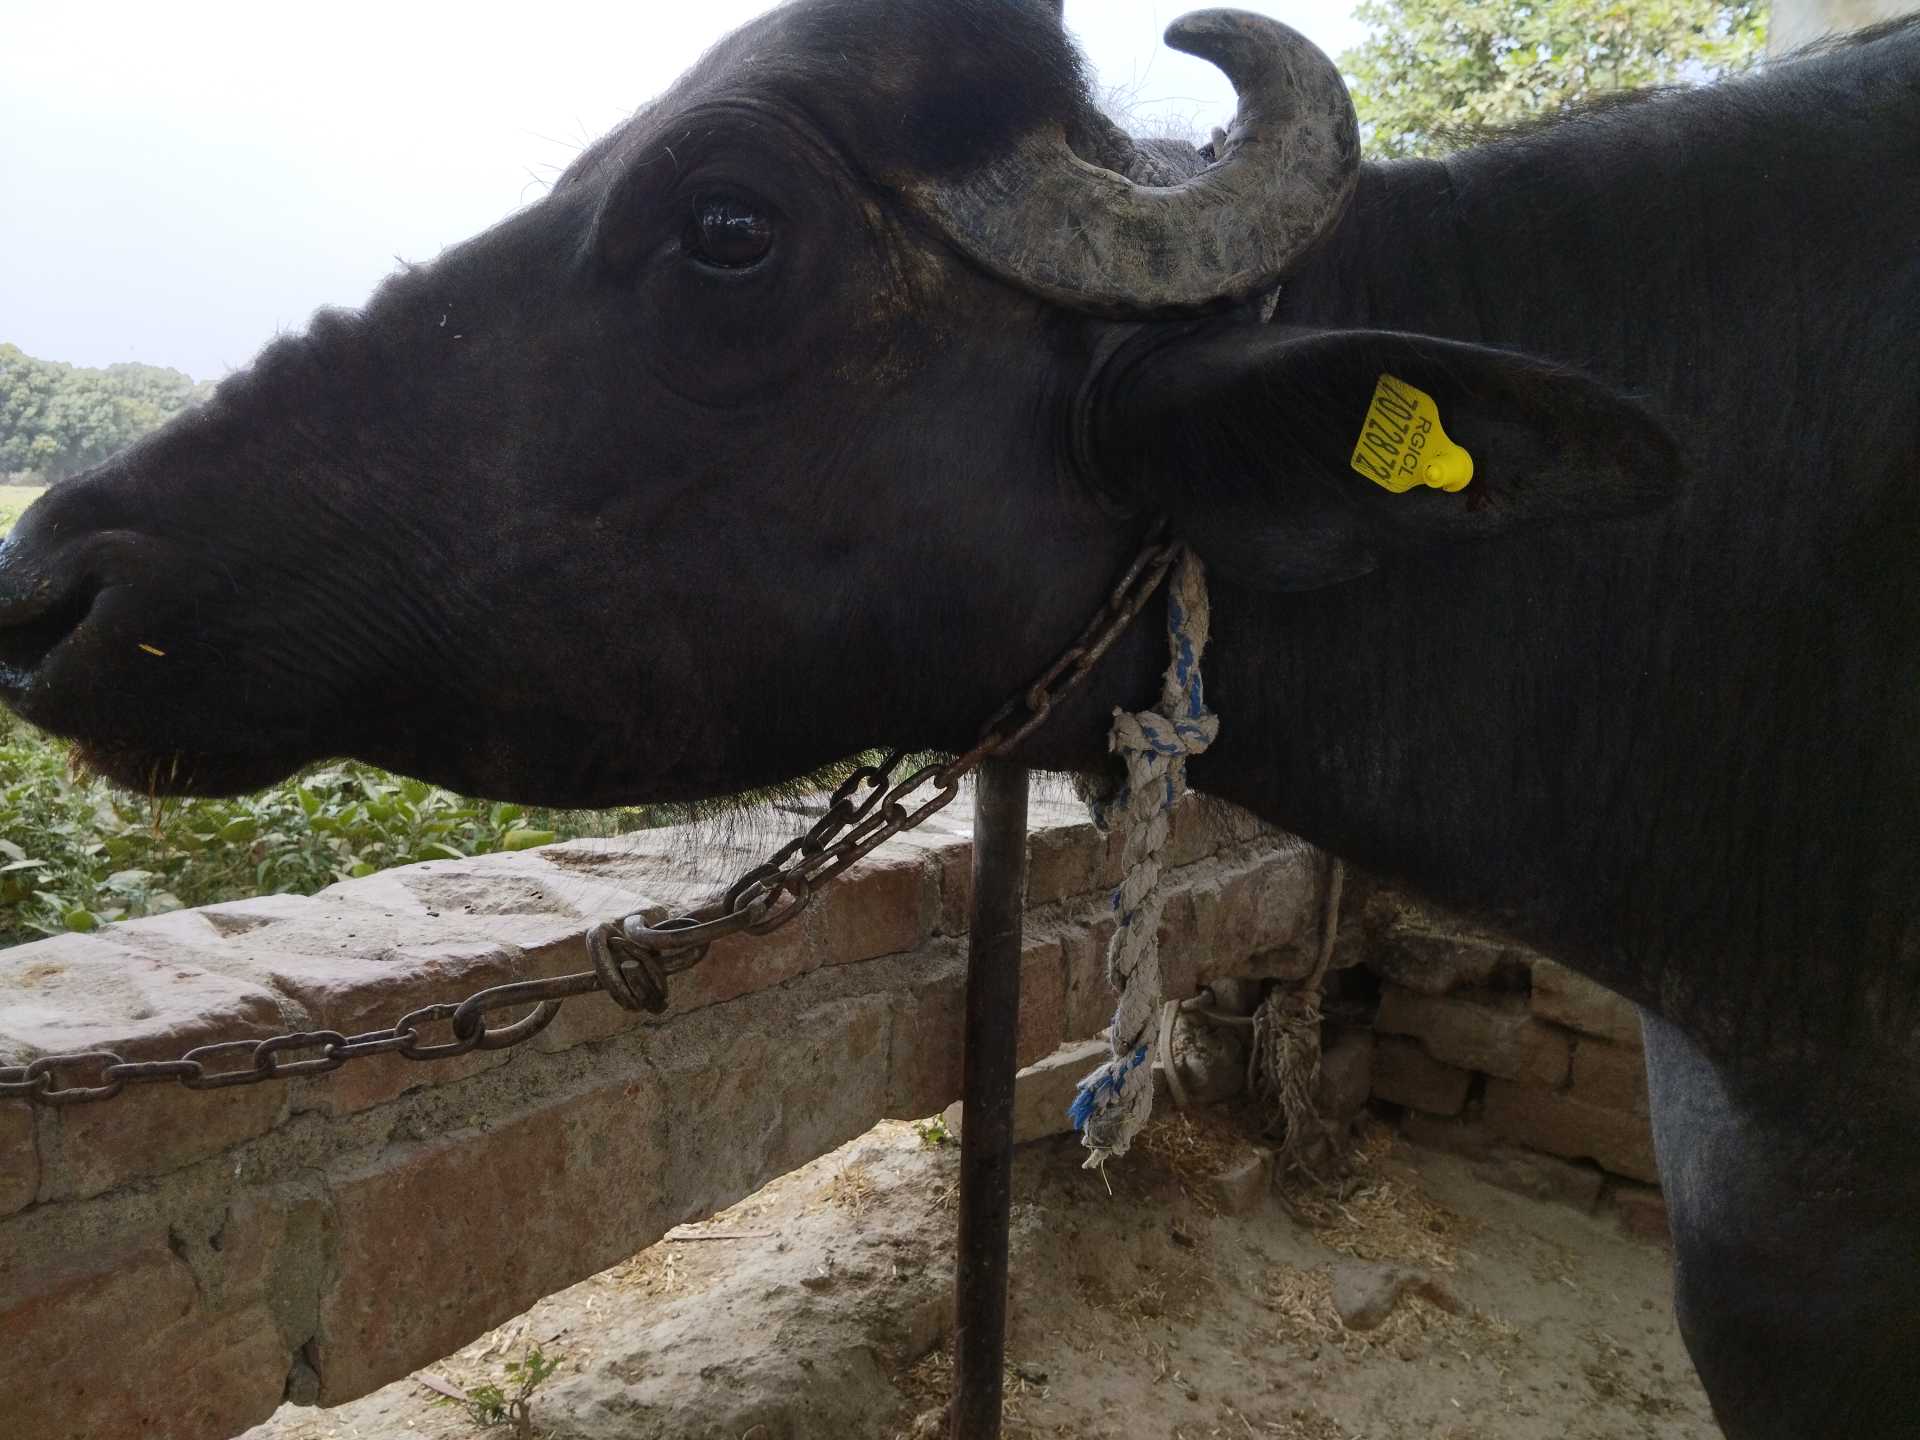
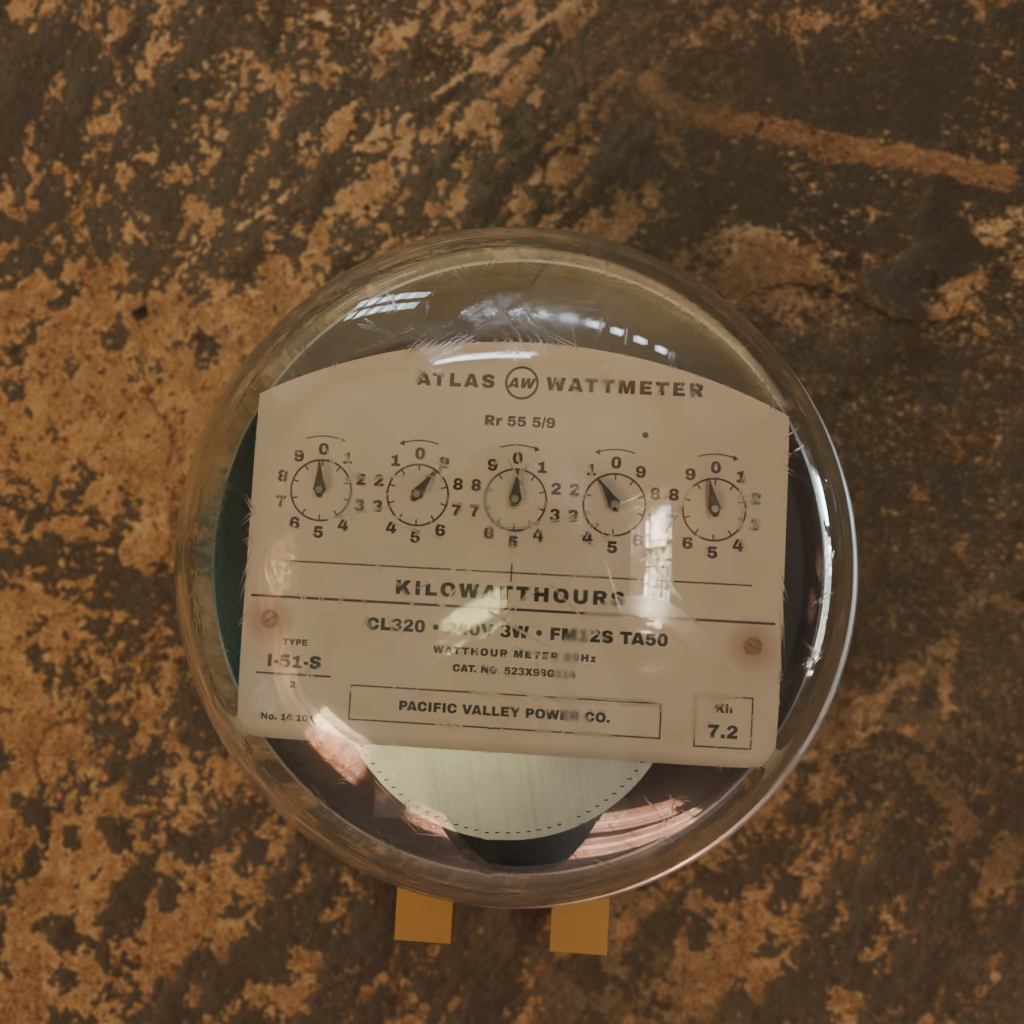
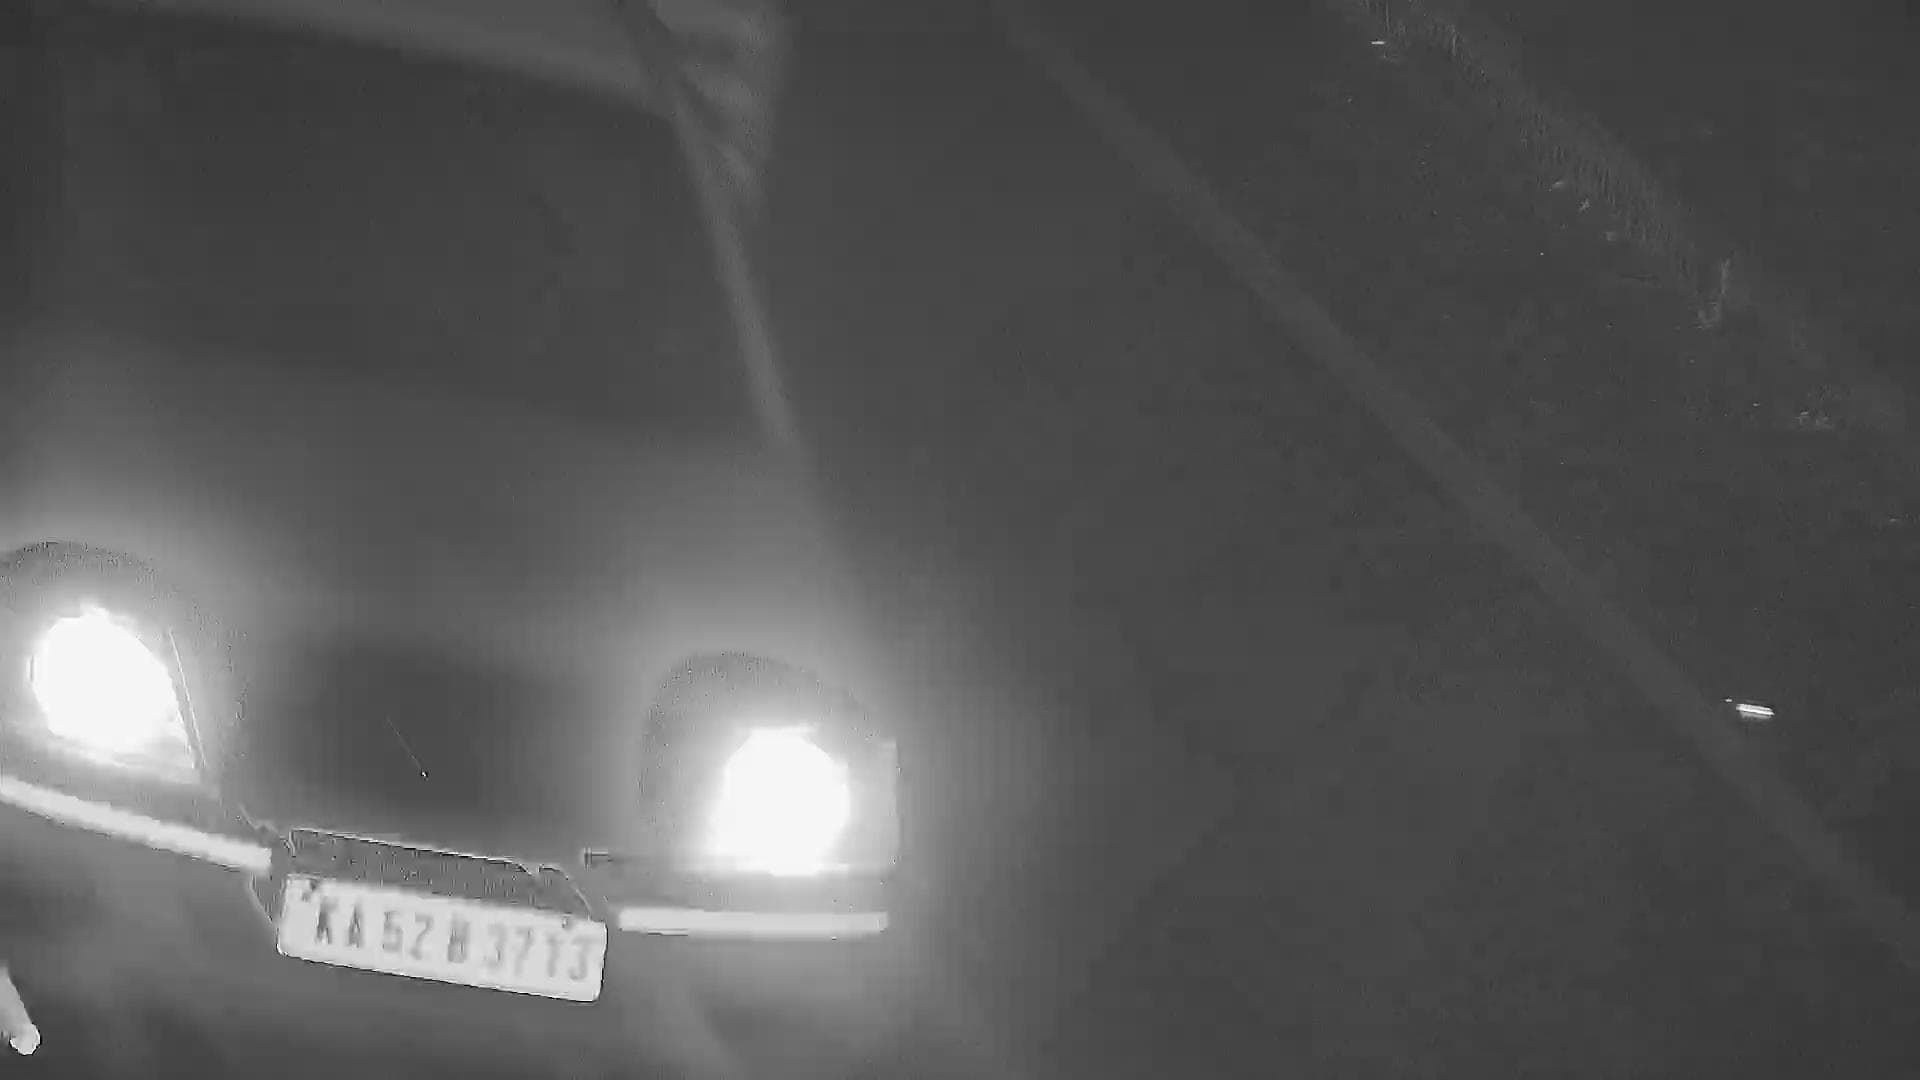
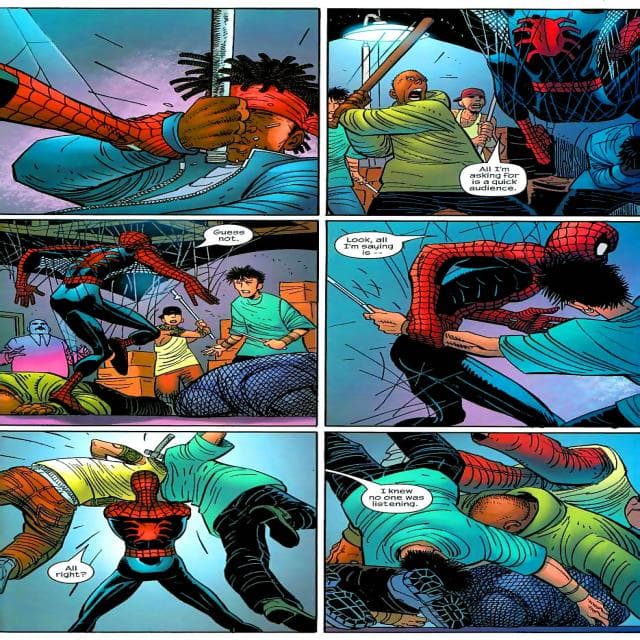
The models are asked
Read the number on the animal’s ear tag. Return only the digits.
Ground truth
7072872
The models are asked
Read the five-dial electricity meter. Return the five-digit reading, including any leading zeros.
Ground truth
99009
The models are asked
Read the largest visible vehicle license plate. Return only its registration number, without spaces; keep letters, digits, leading zeros, and hyphens.
Ground truth
KA52B3713
The models are asked
Transcribe the speech and thought bubbles in reading order, one bubble per line. Preserve capitalization and punctuation; skip captions and sound effects.
Ground truth
All I'm asking for is a quick audience. Guess not. Look, all I'm saying is -- All right? I knew no one was listening.
The models are asked
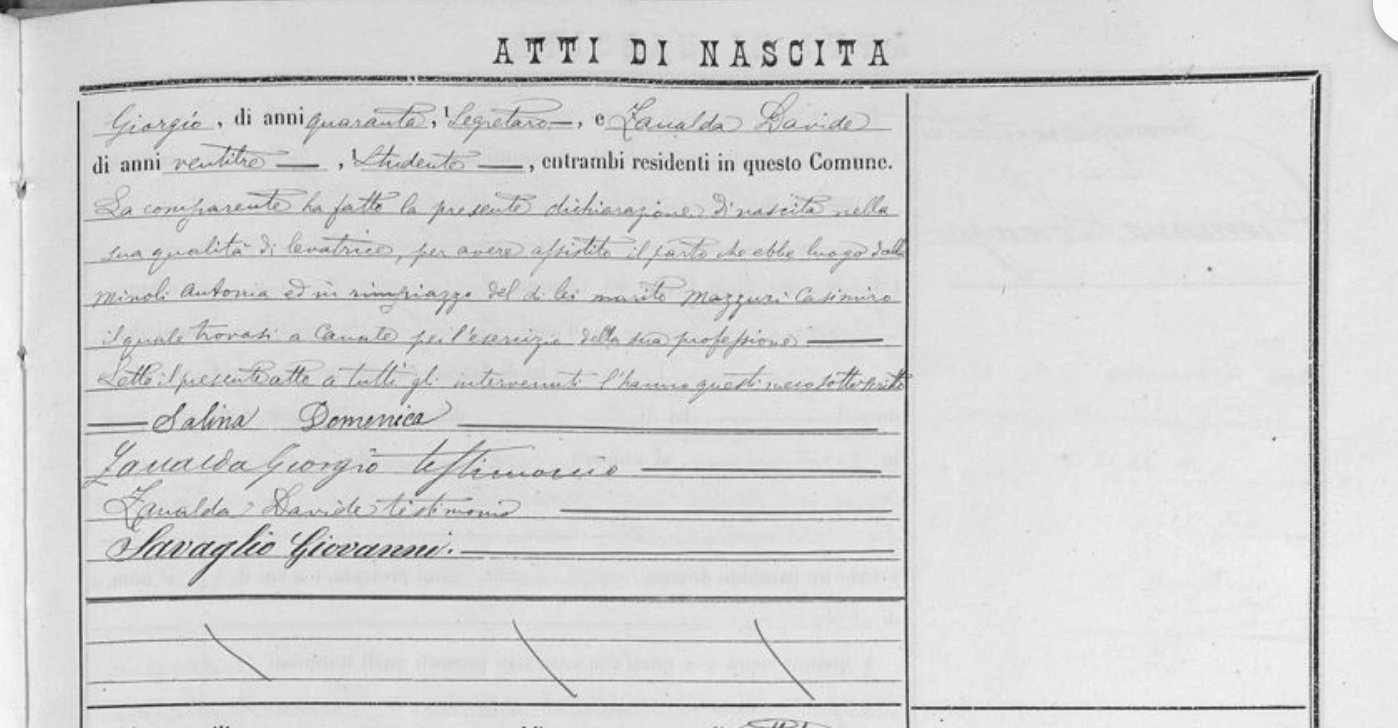
Transcribe all visible text in this Italian document in reading order. Preserve the original spelling, punctuation, and paragraph breaks; do not translate or include blank ruling lines.
Ground truth
ATTI DI NASCITA Giorgio, di anni quaranta, Segretaro, e Zanalda Davide di anni ventitre, Studente, entrambi residenti in questo Comune. La comparente ha fatto …
The models are asked
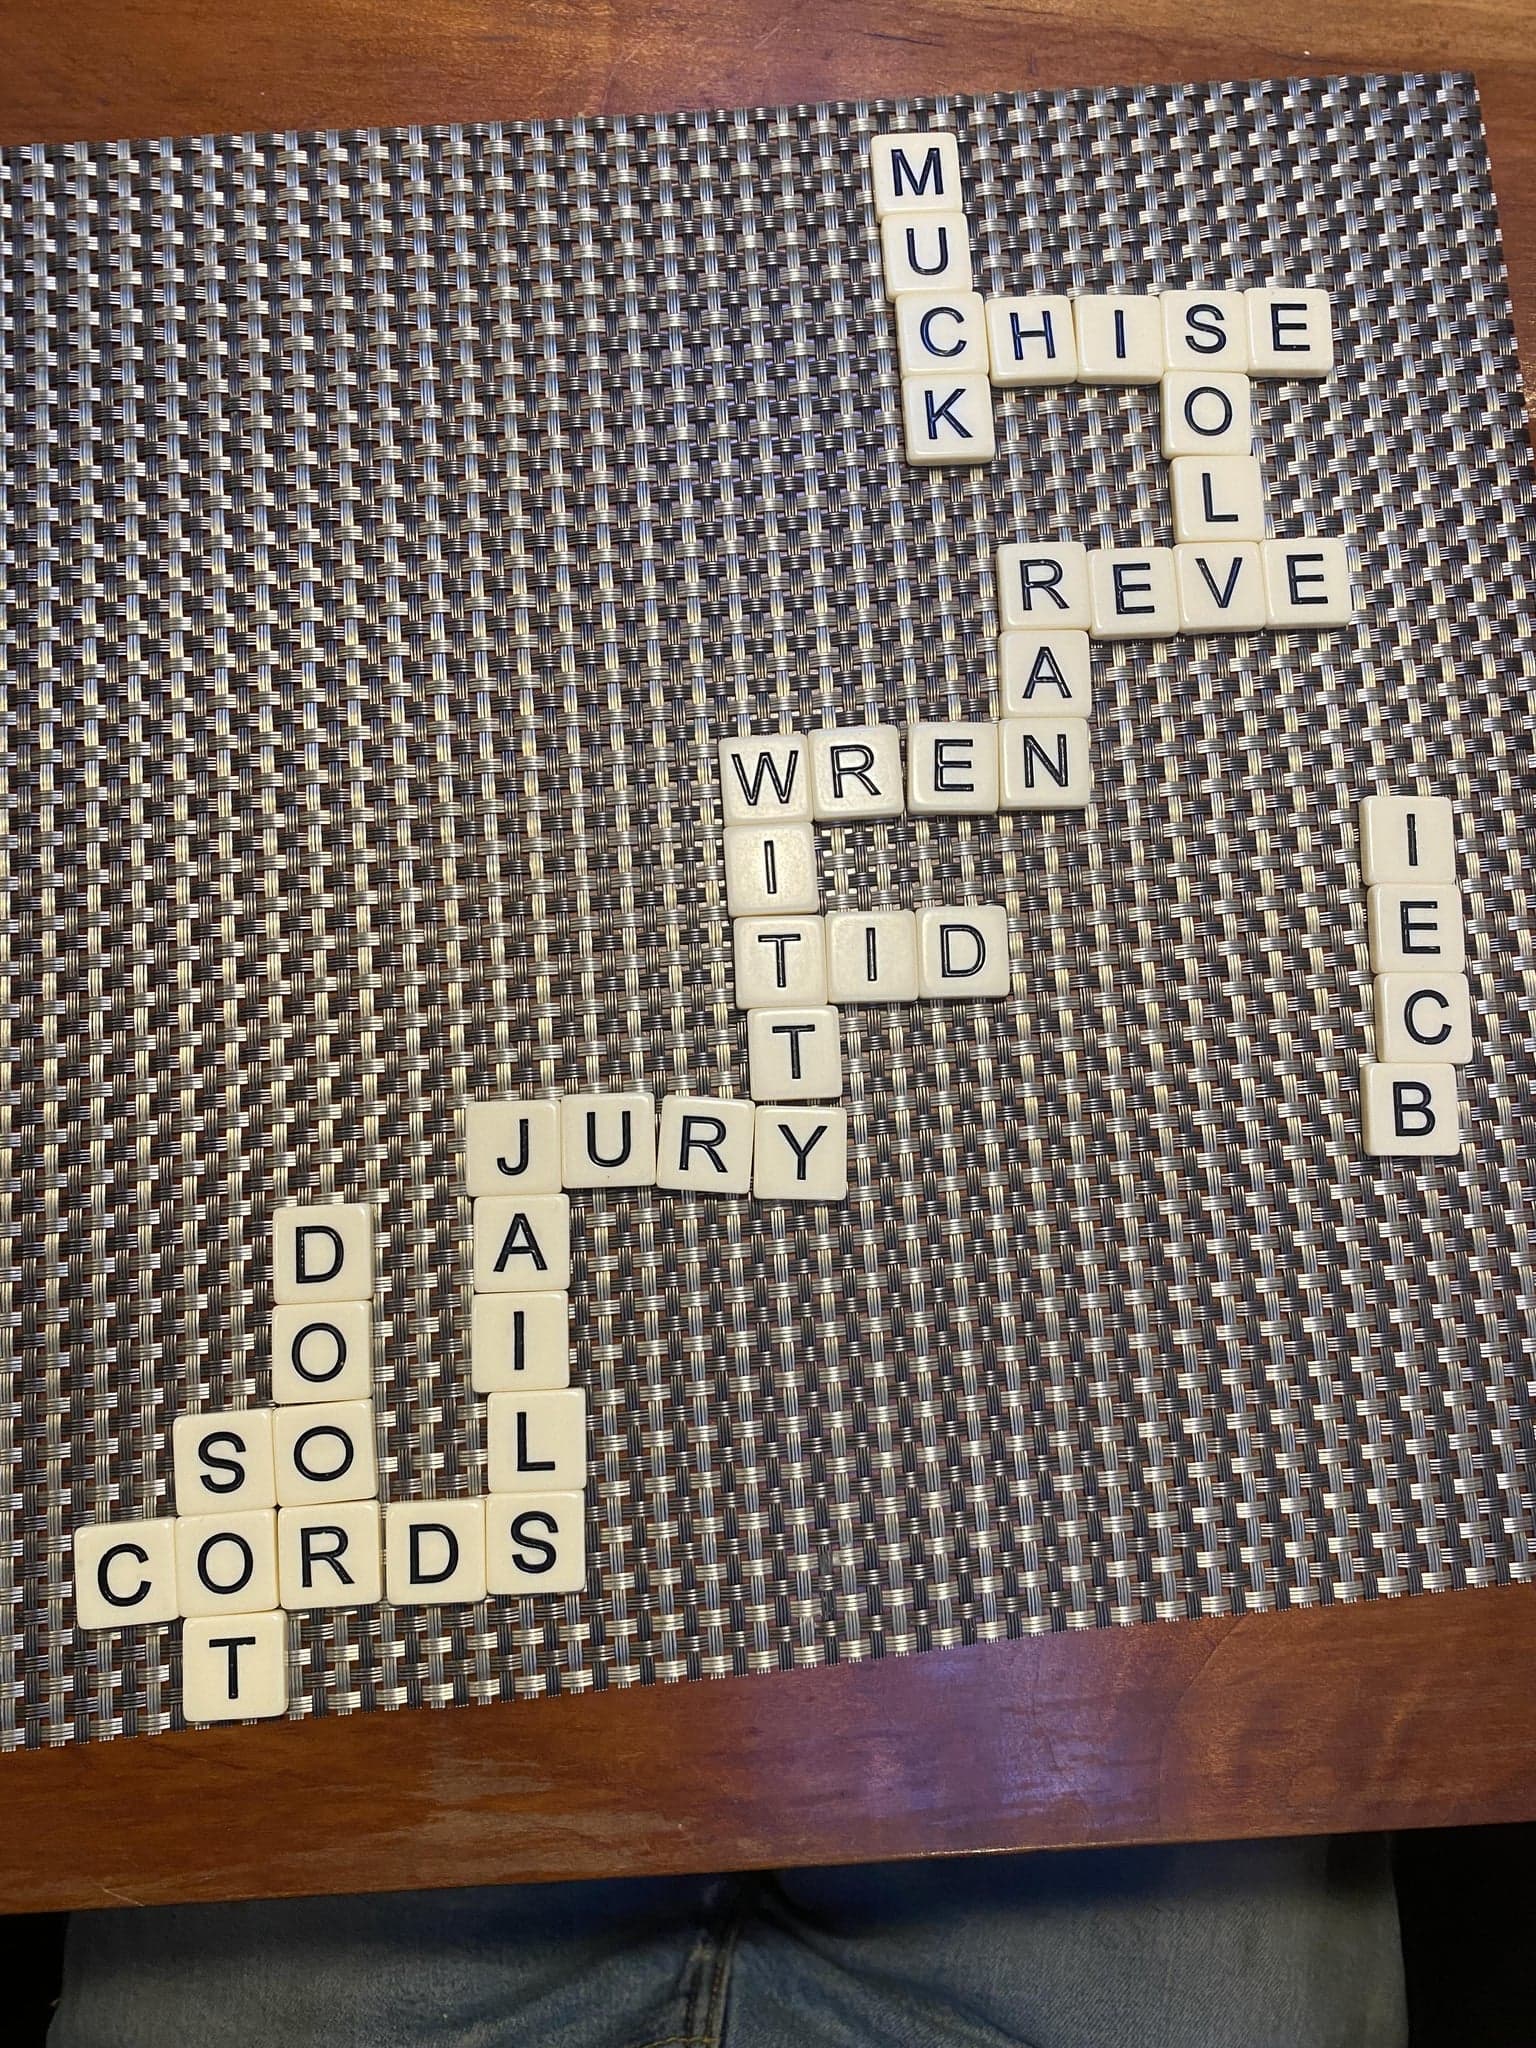
Read the valid Scrabble words formed by the tiles, including rotated words. Return them in uppercase, one per line, in alphabetical order; keep repeated words and ignore isolated letters.
Ground truth
CORDS DOOR JAILS JURY MUCK RAN SO SOT WITTY WREN
The models are asked
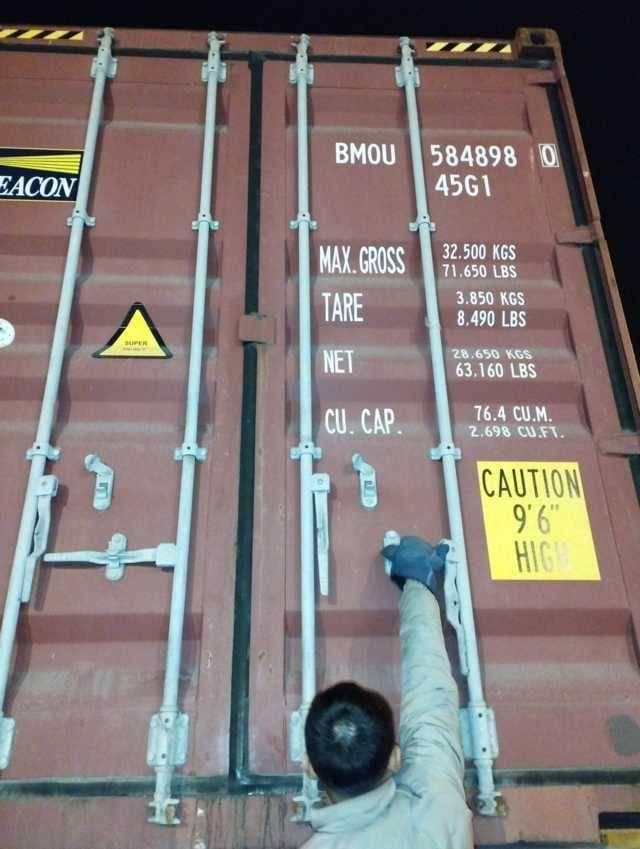
Extract the main shipping container’s markings as JSON with these keys: container_id, size_type_code, maximum_gross_kg, maximum_gross_lb, tare_kg, tare_lb, payload_kg, payload_lb, capacity_m3, …
Ground truth
container_id: BMOU5848980; size_type_code: 45G1; maximum_gross_kg: 32500; maximum_gross_lb: 71650; tare_kg: 3850; tare_lb: 8490; payload_kg: 28650; payload_lb: …
The models are asked
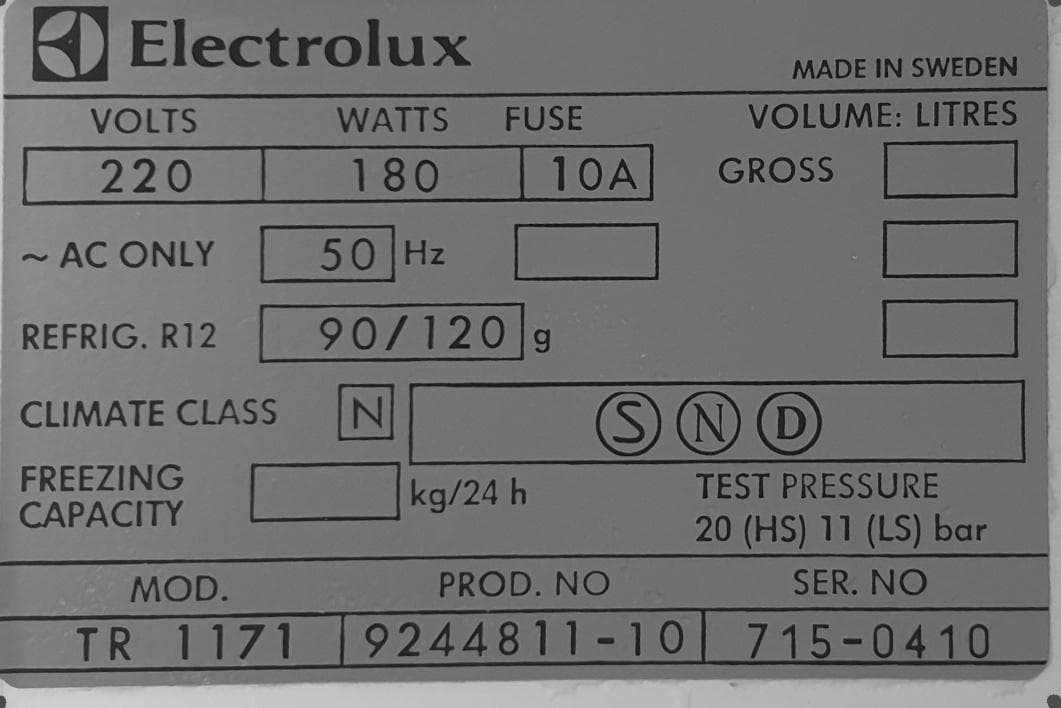
Extract this appliance label as JSON with these keys: brand, model_number, product_number, serial_number, voltage, frequency, refrigerant, country_of_manufacture. Use strings, or null for missing …
Ground truth
brand: Electrolux; model_number: TR1171; product_number: 9244811-10; serial_number: 715-0410; voltage: 220 V; frequency: 50 Hz; refrigerant: R12; …
The models are asked
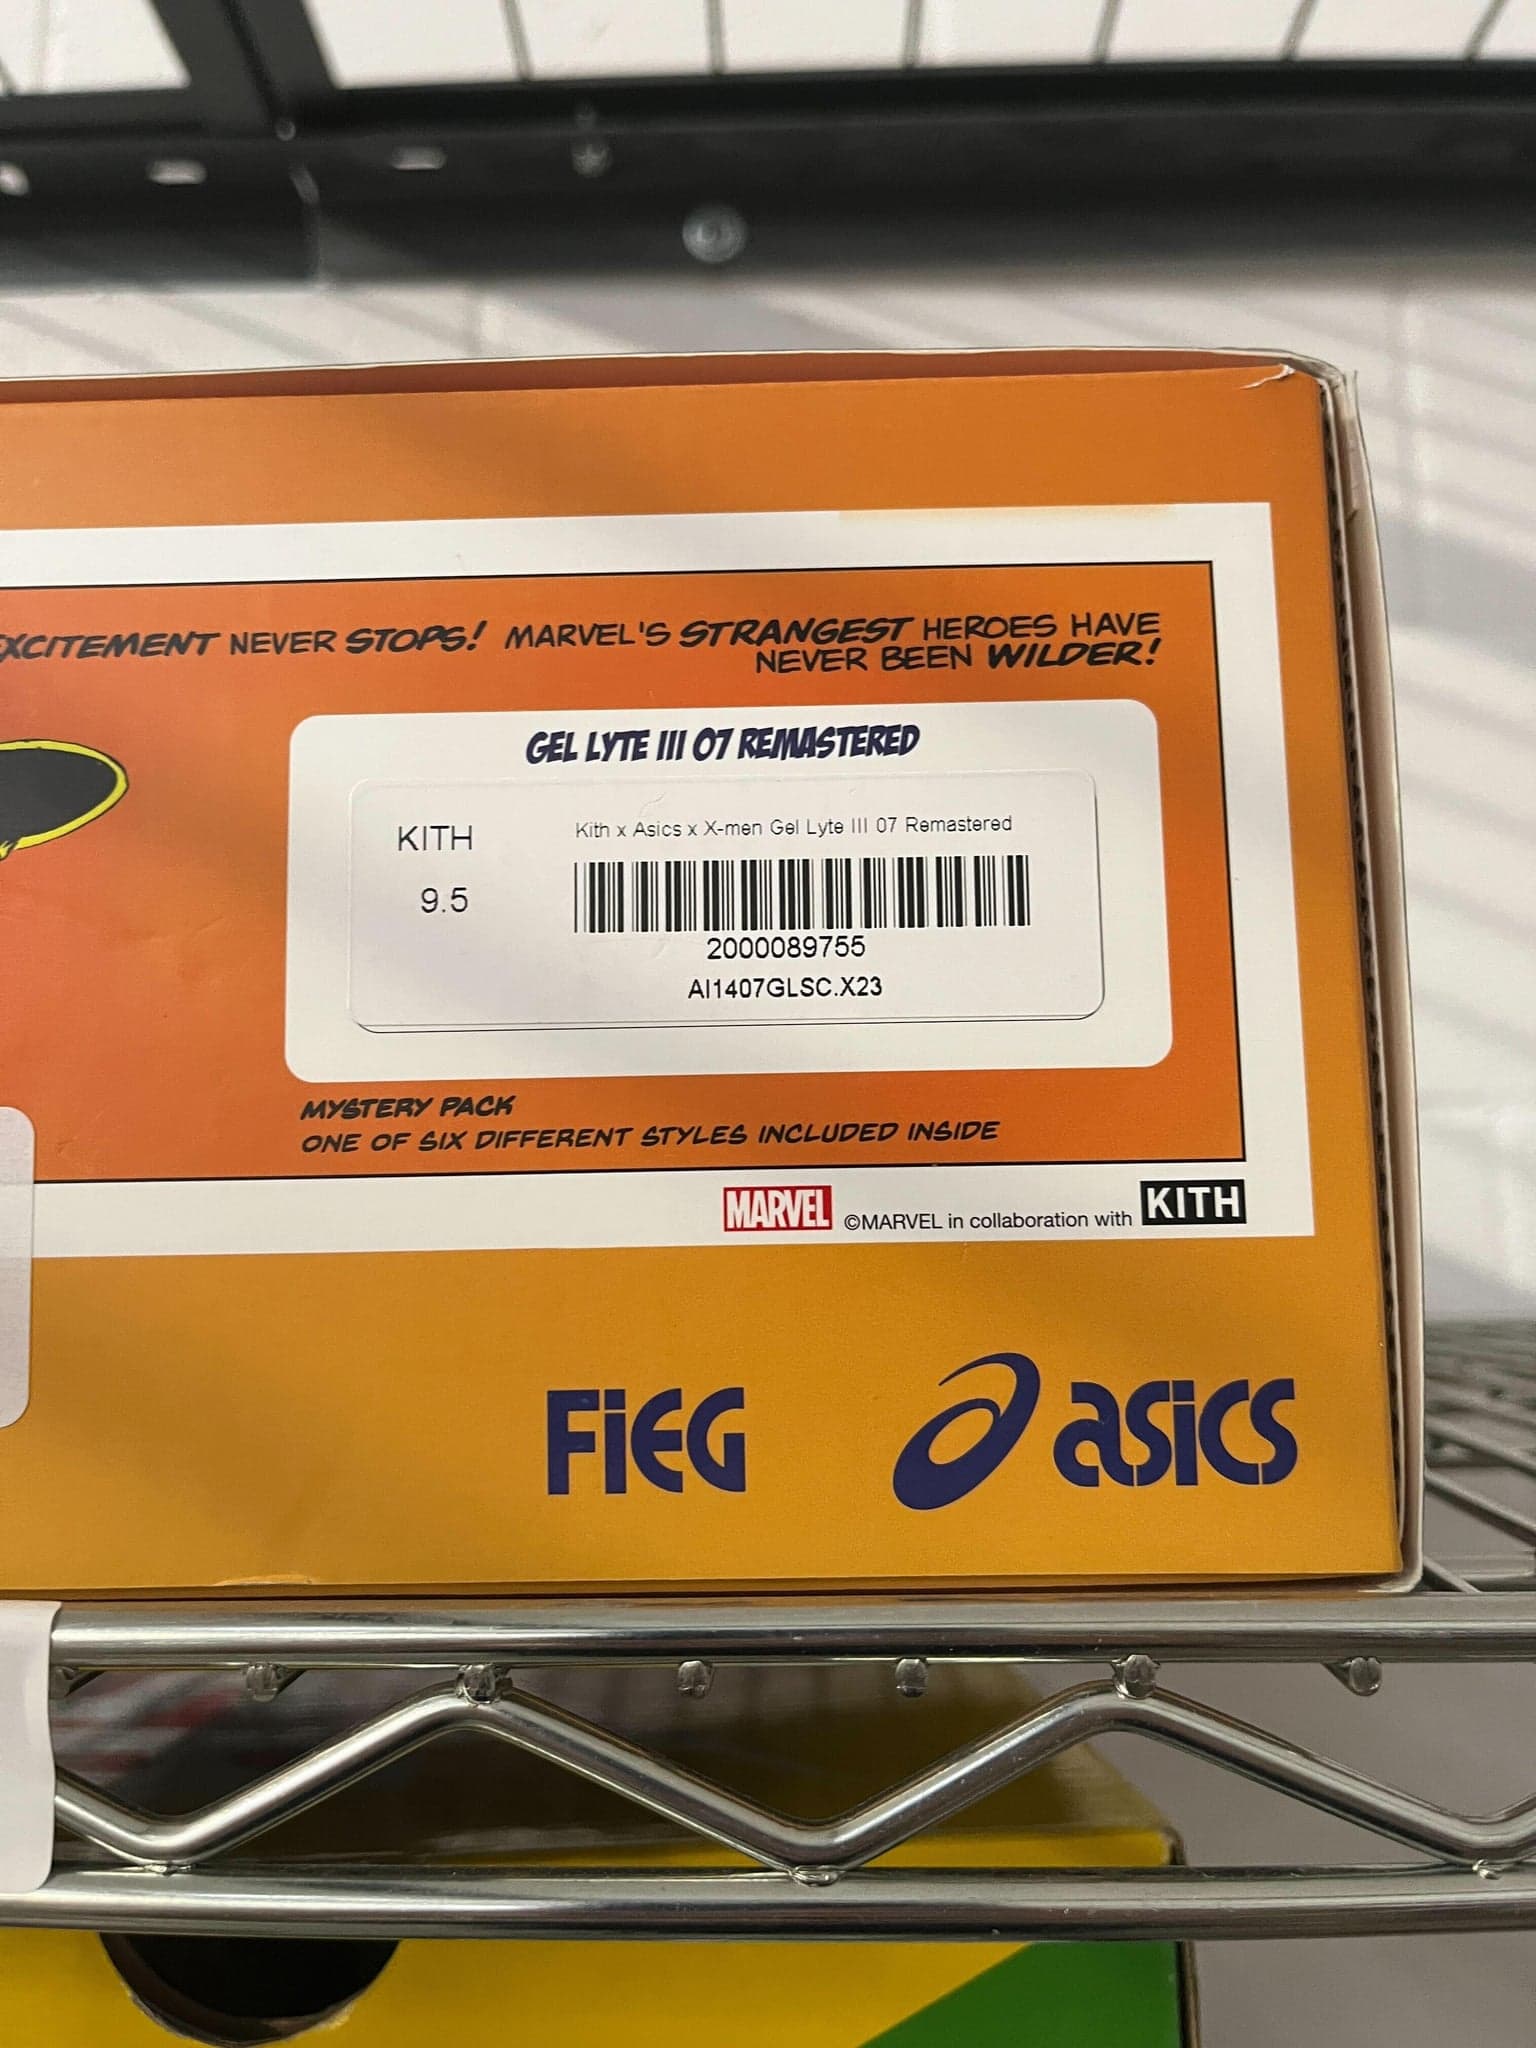
Extract this sneaker label as JSON: {"sku": null, "sizes": {"US": null, "UK": null, "EU": null, "CM": null}, "upc": null}. Use strings for visible values and null for missing fields. Prefer men’s …
Ground truth
sku: AI1407GLSC.X23
The models are asked
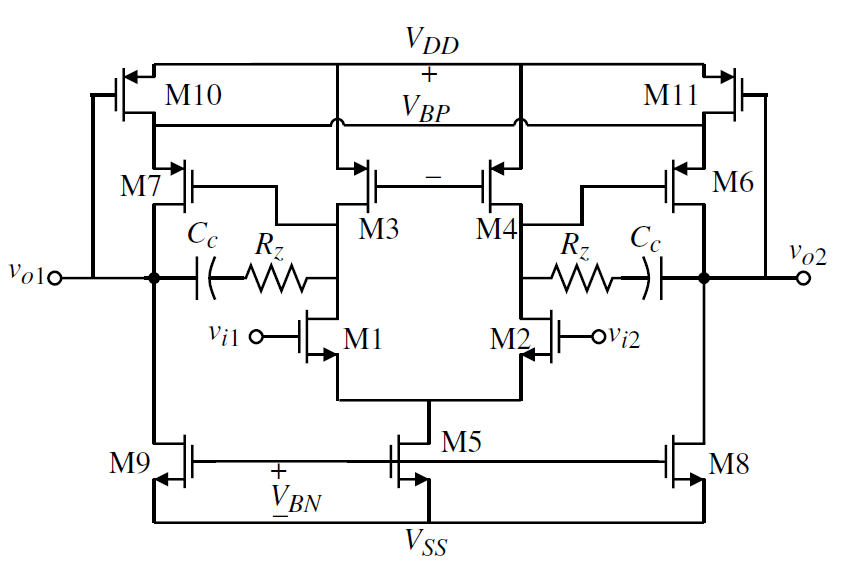
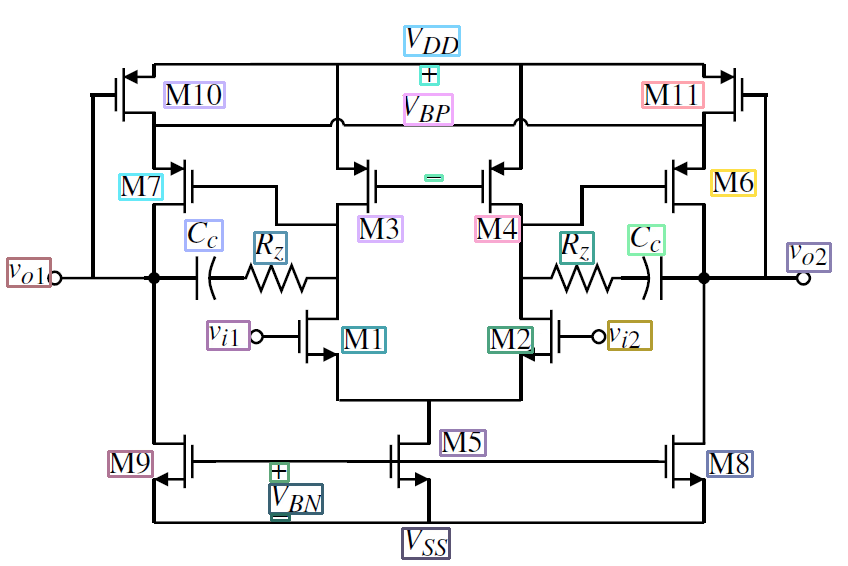
Locate and transcribe each circuit label, value, and polarity mark, including rotated labels. Use tight boxes around individual markings and LaTeX for mathematical text; skip wires and circuit …
Ground truth
27 text regions: V_{DD}, +, M10, M11, V_{BP}, M6, …
The models are asked
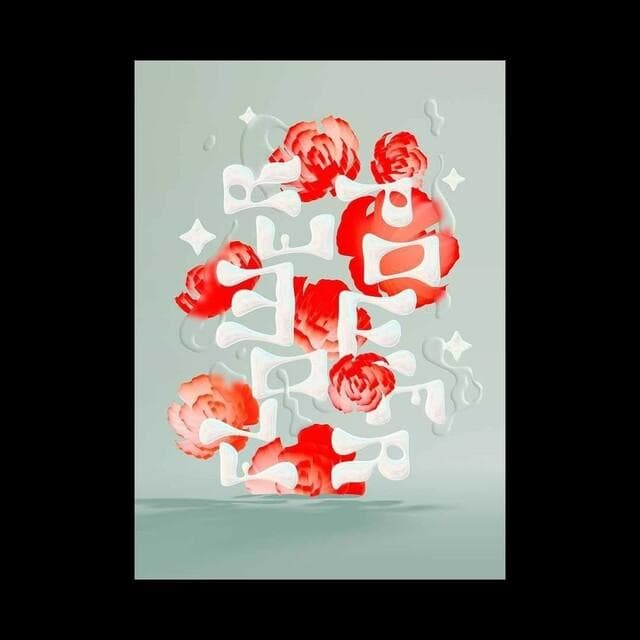
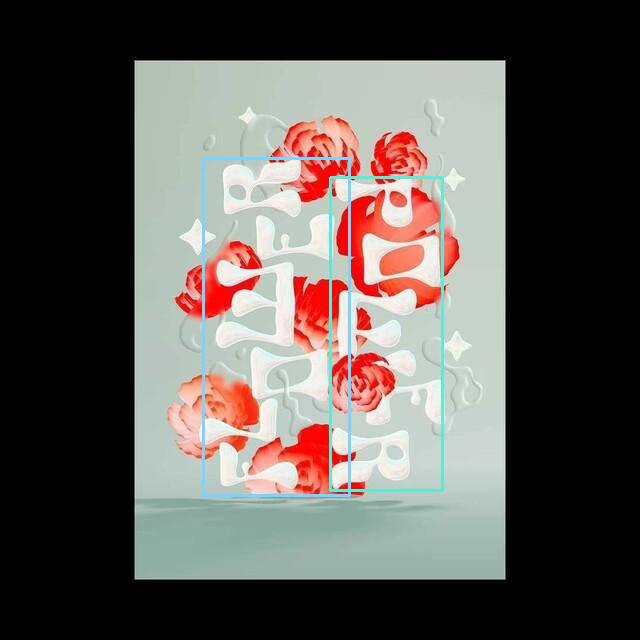
Locate and transcribe the poster’s text, including rotated or curved words. Use a tight box per text line or separate word group; skip decorative graphics. Return a JSON array of {"bbox": [x1, y1, …
Ground truth
2 text regions: FLOWER, POWER
The models are asked
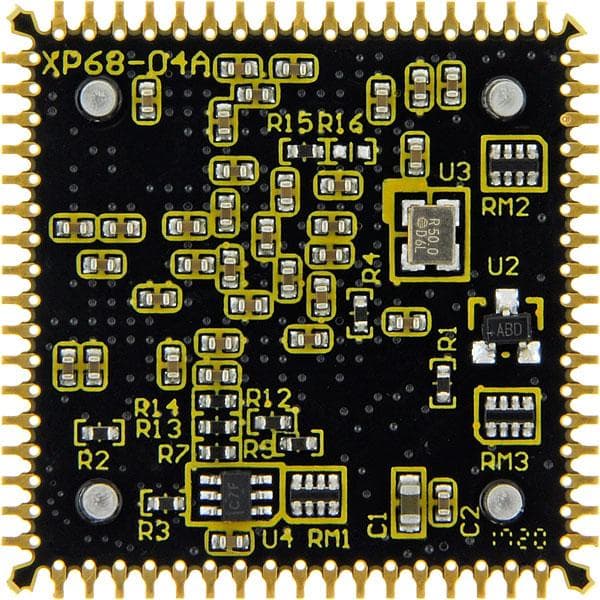
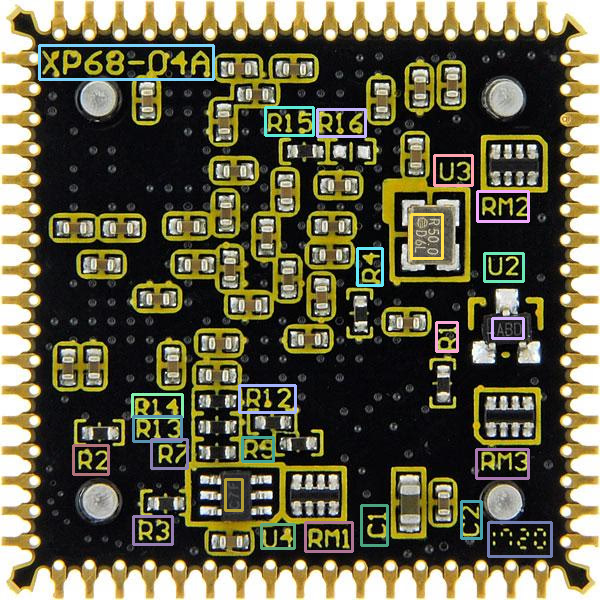
Locate and transcribe all visible markings on the circuit board and its components. Use one tight box per marking, join its lines with spaces, and skip logos and non-text symbols. Return a JSON array …
Ground truth
24 text regions: XP68-04A, R15, R16, U3, RM2, R50.0 D6L, …
How OCR is scored
Every question is scored deterministically against the ground truth, with no LLM judge. Single value answers must match exactly. Transcriptions are scored by character similarity, so a near miss earns partial credit. Structured answers are scored by how many JSON fields match, with missing and extra fields both counting against the model. Located text counts when a box overlaps the ground truth by more than half and its text matches exactly. The headline score is the mean over every question, and each category also has its own column. OCR results are currently a single preliminary run per model, so they carry no ±.
Runs, effort tiers and cost
Every model runs the same sample set. Under the current protocol each task is run three times at each effort tier and the score is the mean over those runs, shown with its ± range in the table; models benchmarked before the protocol ran once per task and are being re-run under it. Token usage is measured from each provider’s API response, and cost per sample is that usage multiplied by the model’s published pricing.
See the full methodology.
Frequently Asked Questions
Each model answers the same questions. Every answer is scored from 0 to 100 against the ground truth by a rule that fits its category, and the headline score is the mean over all of them. Because the categories have different numbers of questions, the headline is not the plain average of the four category columns.
Single value: one reading returned exactly, such as a meter value or tire size. Transcription: all the text in a document or region, scored by similarity. Structured: the fields of a label, ticket, or form returned as JSON, scored field by field. Text localization: every piece of text with its bounding box, which tests whether the model knows where text is, not only what it says.
The OCR results come from one run per model at each effort tier, while the other tasks are averaged over three runs. A single run cannot show how much a score moves between runs, so these scores carry no ± range. They may be re-run three times later.
Every task is run at two levels of reasoning effort. The low row is the model answering with minimal deliberation, the high row is the same model on the same questions allowed to think longer. Both rows are ranked together so you can see whether the extra thinking is worth its cost and latency, which the Est. cost and Speed columns show, and the effort filter above the table shows one tier at a time. Models benchmarked before the current protocol have a high-effort row for Reasoning only until they are re-run. Every other table on this site, including the overall Average, uses the low-effort pass so all models are compared on the same amount of compute.
Under the current protocol each task is run three times at each effort tier, and the score shown is the mean over those runs. The ± is half the range between the lowest and highest run, so it shows how much the score moved between runs; it is a range, not a confidence interval. Hover the ± for the run count and range. A score without one comes from a single run; models benchmarked before the protocol are being re-run under it. OCR results are currently a single preliminary run per model, so they carry no ±.
Most models in this leaderboard link to their Playground page. Click the model name to open it, then upload your own image and run it. A few models are benchmarked for comparison only and do not have a Playground page yet.